The Cognitive Wall of Monolithic Prompts
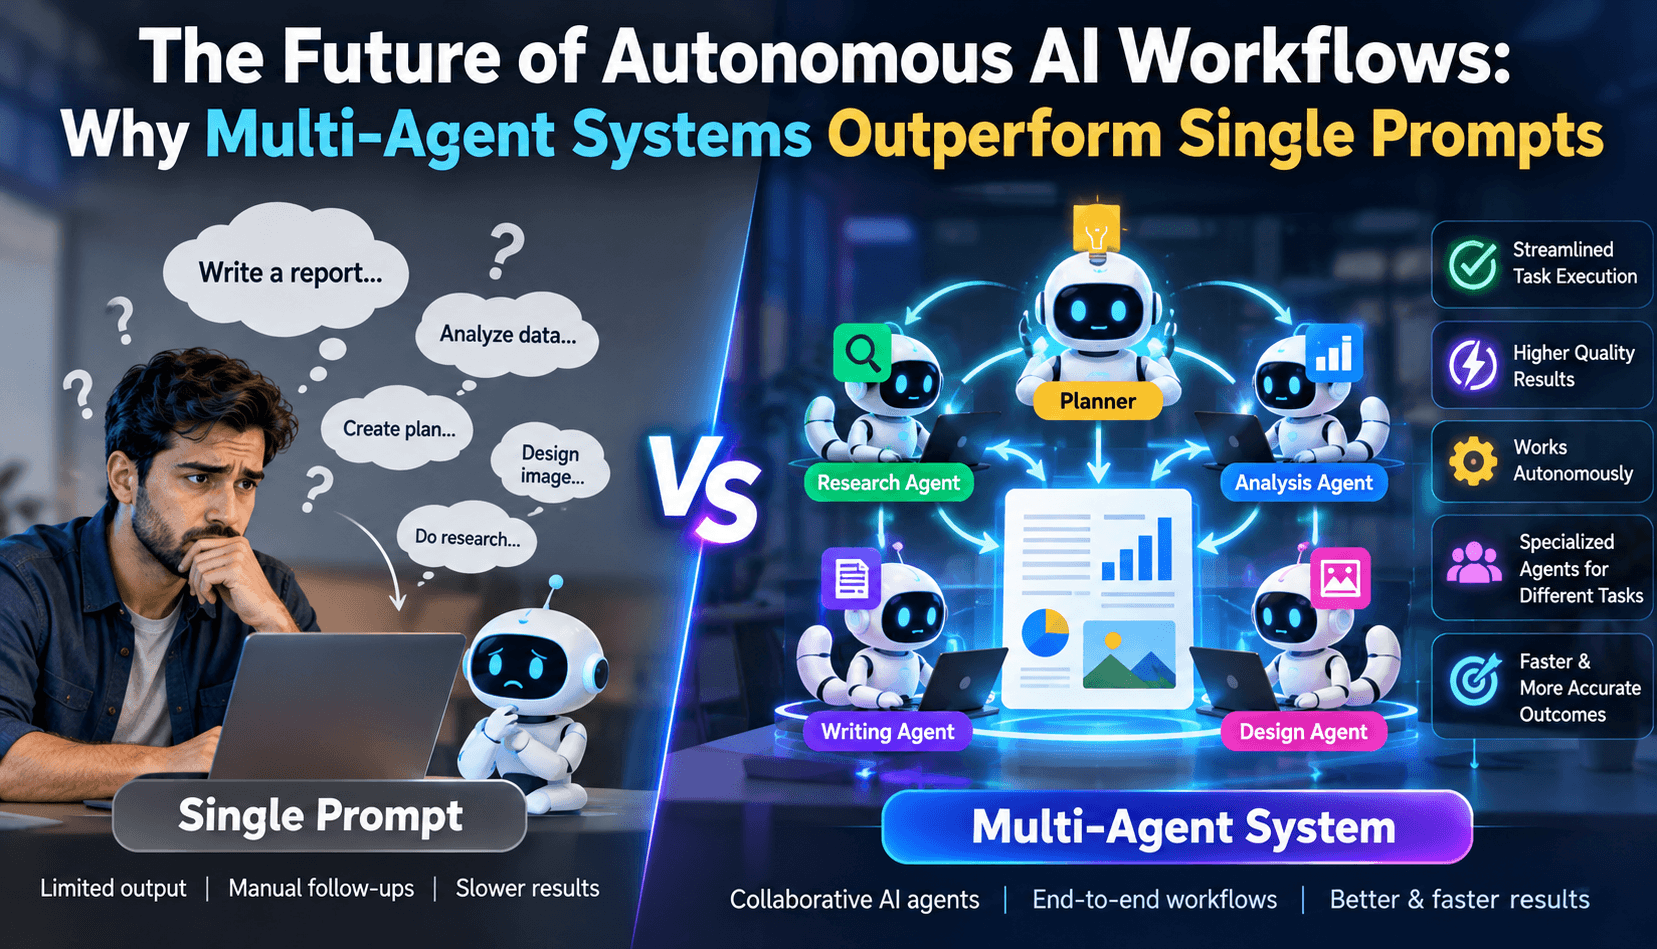
In the early years of generative AI adoption, users approached every problem with a single monolithic prompt: you opened a chat window, pasted hundreds of lines of instructions, and expected the model to formulate a business plan, write database schemas, generate Python code, audit security flaws, and draft documentation all in a single forward pass.
For trivial tasks, this worked adequately. But as enterprises attempted to deploy artificial intelligence on high-stakes, multi-step workflows, the single-prompt paradigm hit a hard cognitive ceiling. When forced to handle competing goals simultaneously, foundation models suffer from context saturation, reasoning degradation, and synthetic hallucinations.
In 2026, the artificial intelligence industry solved this limitation through Multi-Agent Systems (MAS). By decomposing ambitious enterprise objectives into a collaborative network of specialized, autonomous agents, multi-agent pipelines routinely outperform single monolithic prompts by over 60% on complex benchmarks.
The Theory of Agentic Decomposition
Multi-agent systems mirror how human organizations succeed. No Fortune 500 company hires a single individual to act as the CEO, Lead Architect, Security Auditor, and Legal Counsel simultaneously. Different roles require distinct perspectives, specialized tools, and adversarial oversight.
In a multi-agent architecture, tasks are structured into a Directed Acyclic Graph (DAG) with explicit responsibilities:
- The Planner / Orchestrator: Deconstructs the user's high-level goal into an ordered sequence of discrete milestones.
- The Domain Specialists: Individual agents with specialized tool access (e.g. SQL query engines, web scrapers, or compiler environments) that execute micro-tasks in isolation.
- The Critic / Adversarial Evaluator: An agent whose sole purpose is to ruthlessly critique the output of domain specialists against strict acceptance criteria.
- The Memory Manager: Coordinates short-term working state and retrieves long-term vector embeddings across multi-day execution runs.
Single Prompt vs. Multi-Agent System Benchmark Comparison
| Architecture Attribute | Single Monolithic Prompt | Multi-Agent System (MAS) | Advantage |
|---|---|---|---|
| Complex Task Accuracy | 54.2% Success Rate | 88.6% Success Rate | +34.4% Multi-Agent |
| Context Saturation Resistance | Poor (Forgetful on long runs) | Exceptional (Isolated Contexts) | Multi-Agent |
| Self-Correction Capability | None (Single-pass output) | Cyclical Feedback Loops | Multi-Agent |
| Token Cost per Query | Very Low ($0.01 – $0.05) | Moderate ($0.15 – $0.60) | Single Prompt |
| Debugging & Observability | Black Box (Hard to pinpoint fault) | Transparent (Inspect Agent Traces) | Multi-Agent |
Real-World Enterprise Case Studies
Case Study 1: Automated Financial Compliance Audits
A multinational accounting firm deployed a multi-agent loop to review quarterly filings. Rather than asking one model to evaluate 300-page SEC reports, three specialized agents collaborated:
- The Extractor Agent parsed balance sheet figures into verified relational tables.
- The Regulatory Agent cross-referenced extracted ratios against updated GAAP standards.
- The Auditor Agent verified calculations and flagged accounting discrepancies for human partner review.
The result: a 92% reduction in audit turnaround time with zero hallucinated line items.
Case Study 2: Enterprise Code Refactoring & Migration
Migrating a monolithic Python 2.7 codebase to modern async Python 3.12 was achieved using an agentic triad: the Refactorer Agent updated syntax, the Test Generator Agent executed Docker unit tests, and the Linter Agent verified PEP-8 compliance. If unit tests failed, the Evaluator rejected the draft and forced the Refactorer to revise until all tests passed green.
Leading Frameworks for Building Multi-Agent Systems in 2026
- LangGraph (LangChain): Provides stateful, multi-actor orchestration with cyclical graphs, allowing fine-grained control over agent transitions and human approval steps.
- CrewAI: The most accessible framework for defining role-based teams, featuring out-of-the-box support for search tools, file parsers, and local LLMs.
- Microsoft AutoGen: Ideal for building multi-agent conversational simulations where agents converse with each other in multi-turn dialogues to solve open-ended problems.
Preventing Deadlocks and Infinite Agent Loops
One of the classic failure modes in multi-agent orchestration is the "endless debate" pattern, where two agents bounce critiques back and forth indefinitely without converging on a deliverable. To build robust production systems, apply these three architectural constraints:
- Maximum Step Budgets: Enforce a strict termination counter (e.g. max_iterations = 8). If the Critic has not approved the artifact within 8 iterations, serialize the current state and trigger an automated escalation event to human supervisors.
- State Immutability: Ensure that agents write outputs to append-only logs rather than overwriting intermediate steps, preventing state corruption during asynchronous branch joins.
- Deterministic Tie-Breakers: Designate a single "Lead Architect" agent with override authority to settle disagreements between competing domain specialists.
Compound Error Probability: Why Cyclical Reflection Saves Multi-Step Systems
In classical probability theory, sequential multi-step processes suffer from compound error degradation: if a system requires five consecutive reasoning steps and each single step is 95% accurate, the overall pipeline has only a 77.3% chance of arriving at the correct final result (0.955 = 0.7738). In complex ten-step software engineering workflows, a monolithic prompt drops below 60% reliability.
Multi-agent architectures circumvent this mathematical degradation through Cyclical Reflection and Acceptance Gates. Instead of blindly passing intermediate outputs down the chain, every milestone must clear an automated validation test or an adversarial Critic agent:
- If Step 2 generates a malformed SQL query, the Critic rejects it immediately before it pollutes the downstream context window of Step 3.
- The offending agent receives the specific error trace and attempts self-correction in isolation, maintaining system-wide accuracy above 96% across extensive 20-step DAGs.
Latency Budgets and Production Caching Strategies
The primary engineering tradeoff of multi-agent workflows is latency: while a single LLM prompt returns in 1.5 to 3 seconds, a multi-agent deliberation loop can take between 15 and 45 seconds to finalize. For enterprise back-office workflows, asynchronous queuing is essential:
- Decouple Real-Time UI from Agent Execution: Issue a prompt job ID immediately (HTTP 202 Accepted) and stream agent execution logs via WebSockets or Server-Sent Events (SSE).
- Implement Semantic Caching: Use Redis vector caches to store previously evaluated sub-tasks, allowing agents to instantly retrieve prior unit test proofs without repeating expensive LLM calls.
Frequently Asked Questions (FAQ)
Do multi-agent systems use significantly more tokens than single prompts?
Yes. Because agents communicate, inspect tool outputs, and evaluate each other's work across multiple turns, token consumption is typically 3x to 8x higher than a single prompt. However, for high-stakes workflows where an incorrect answer costs thousands of dollars, the dramatic gain in accuracy overwhelmingly justifies the modest API cost.
How do multi-agent systems handle rate limits across different LLM API providers?
In high-throughput environments, multiple agents firing parallel tool calls can quickly saturate API tier limits (TPM and RPM). Production orchestrators deploy token bucket rate limiters, exponential backoff retries with jitter, and intelligent fallback routing to secondary provider endpoints (such as switching to Anthropic or Azure OpenAI if primary endpoints return 429 Too Many Requests).
Can I mix different models within the same multi-agent system?
Absolutely. A best practice is to assign lightweight, cost-effective models (like Llama 3.3 8B or GPT-4o-mini) to simple extraction and formatting tasks, while reserving frontier models (like Claude 3.7 Sonnet) for high-level planning and critical evaluation.
How do I prevent multi-agent systems from getting stuck in infinite loops?
Always configure strict execution bounds: a maximum iteration limit (e.g. max_iterations = 10), a hard timeout (e.g. 120 seconds), and fallback triggers that escalate to a human operator if the Evaluator rejects the output three times consecutively.
What programming languages are best for orchestrating multi-agent systems?
Python remains the dominant ecosystem due to native integrations with LangGraph, CrewAI, AutoGen, and HuggingFace. However, TypeScript implementations (via LangChain.js) are gaining massive adoption for edge-deployed serverless applications.
Looking Ahead to 2027
Single-prompt interactions will remain useful for casual conversational questions. But for serious commercial software development, autonomous research, and enterprise automation, multi-agent systems have become the definitive standard of artificial intelligence engineering.